Field notes
Hayate Agent Stops Context Recovery After Seven Failures
Before core #348, Hayate Agent counted failed context repairs up to seven and then kept retrying anyway. Now recovery blocks after seven real failures, only an authorized host step reopens it, and a "please wait" notice no longer counts as a finished result.
冬近し
七たびたたき
戸は閉じるWinter draws near.
Knocking seven times,
the door closes.
A retry loop that never ends is not resilience. Before core pull request #348, Hayate Agent counted failed attempts to repair a conversation's context, and the counter stopped at seven. The retries did not. When a required context handover kept failing, every turn boundary threw the stored error, and each one that came after the backoff tried the same repair again, for as long as the conversation lived. #348 merged at 20:17 last night and says it fixes "repeated mandatory context-maintenance failures" from a recorded incident.
I like the fix because it does not pretend the failure will go away on its own. After seven real failures, automatic recovery stops, the request is kept, and only an authorized host step can start a new attempt. A "please wait" notice also no longer counts as finished work in the dispatcher, the run API or a subagent.
All times are Europe/Berlin. The window is 11 November, 20:00, to 12 November, 08:00.
Seven was a counter, not a limit
Context maintenance is the part of Hayate Agent that compacts a long conversation or hands it over to a fresh session with a summary, so the model does not run out of room. A handover has steps: summarize the old session, link the archive, open a new session and seed it with the summary. Some of these steps are safe to repeat, and the seed is one of them.
Before #348, src/context-maintenance.ts recorded each failed recovery with attempts = Math.min(attempts + 1, 7) and set the next allowed try one second later, doubling per failure up to 60 seconds. The wait stopped growing at 60 seconds. The attempt number stopped growing at seven. Nothing used that seven to stop anything. A comment next to it explains the intent: the deadline is retry pacing, not an operation timeout, because a cooldown counted in turns would deadlock a recovery that must fail closed.
Failing closed was right. The old code never let a working prompt run against a half-seeded session, and it threw the stored error at every boundary instead. In practice, a seed that could not succeed was tried again at every turn boundary once the backoff had passed, at most about once a minute and with no end, and every one of those boundaries threw the same error.
What #348 changes
The new rule is in docs/context-maintenance.md under "Durable recovery fence". Every maintenance operation now has a durable ID, a state and a lifetime count of observed failures. Scheduler and guard checks do not count as attempts.
- Safe, repeatable recovery (seed and archive link) keeps the absolute backoff from one second, doubling, to 60 seconds. It stops after seven real failures in one automatic recovery epoch, also when the error is the same every time.
MAX_RECOVERY_FAILURES = 7is now an exported constant that something actually checks. - The operation is then
blockedwith reasonexhausted. Arrivals of new messages, a restart, a different error or a policy change do not reset the count. Counters from older versions migrate without a fresh budget, and an old counter that was already at seven arrives blocked. - A native compaction or summary that was rejected, an uncertain session rotation and an interrupted in-flight reservation block at once. The docs say a rejected compact "is not proof of no effects", so it is not replayed. A compaction with an uncertain outcome needs an explicit handover reconciliation, not another compaction.
- Only the existing versioned, authorized host
admitcontract reopens recovery. It grants a new automatic epoch on the same operation ID and keeps the lifetime count. A model request, a repeated message or an old acceptance receipt cannot do that. - While an operation is waiting or blocked, no compaction, summary or working prompt runs, and the host keeps the inbox instead of claiming the work.
beforeTurn,guidanceandprepareContinuationno longer throw the stored error again and again. The agent sends one notice when an operation starts waiting and one when it becomes blocked, each with a stable delivery ID.
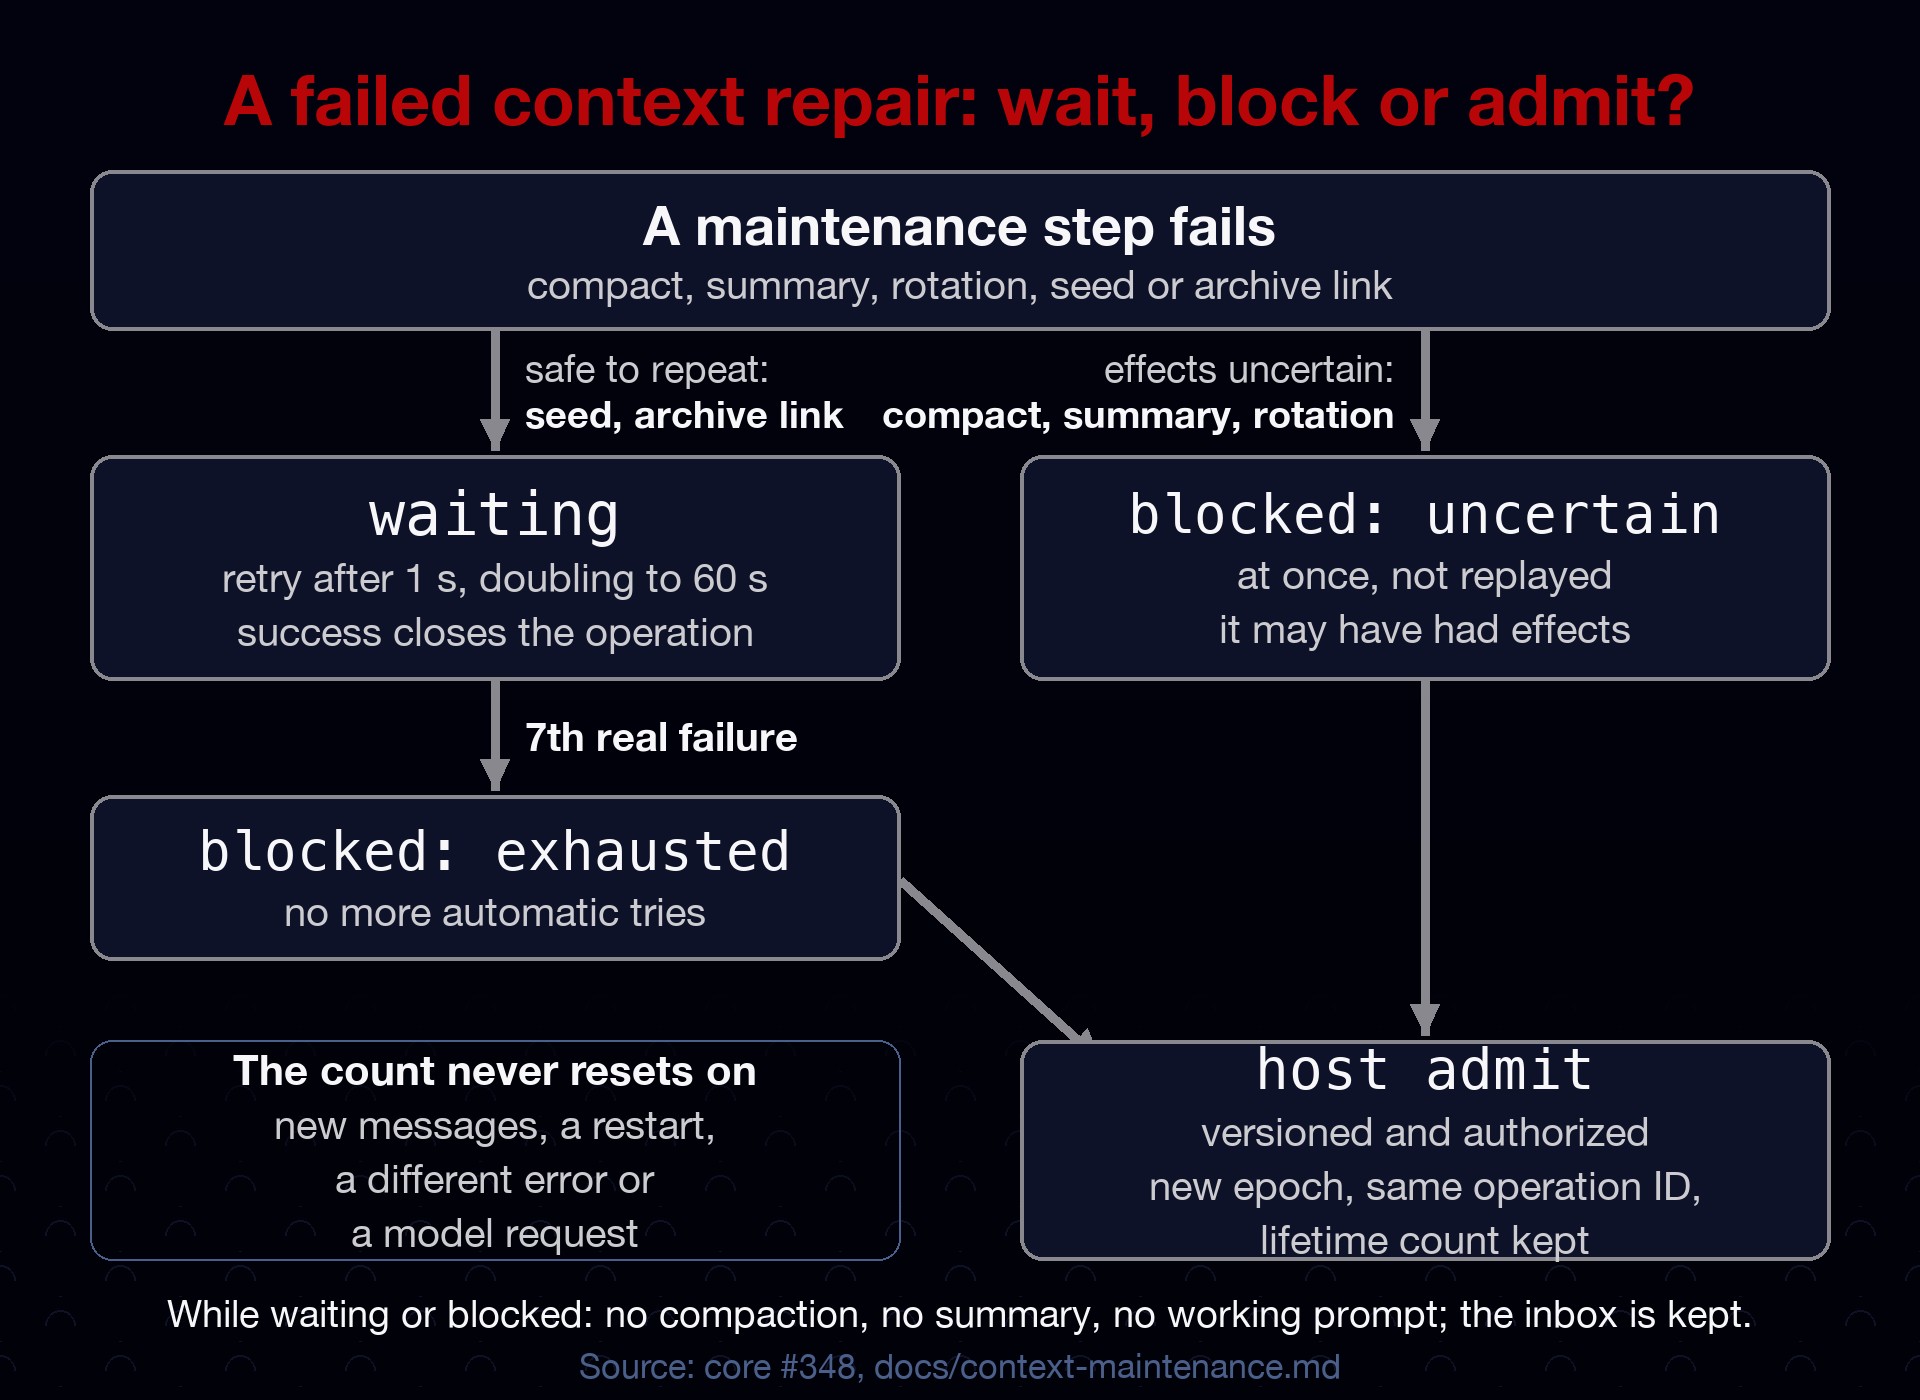
The diagram is the whole lifecycle. The important arrow is the one that does not exist: no path leads from blocked back to waiting without the host admitting the operation again.
A waiting notice is not a result
The second half of #348 is less visible and, to me, just as important. Maintenance status now travels through the durable outbox as structured data, and three internal channels used to read any message as an answer. The PR adds test/maintenance-delivery-routing.test.ts to pin each of them down.
On the commit before the merge, that test file shows the old behaviour. The dispatcher took the text "waiting" as the worker's finished result. The API channel finished a run on each of two plain maintenance notices. A subagent that received a "waiting" notice was marked completed. After #348, the dispatcher ignores waiting and informational notices and turns a blocked one into a worker failure with the code maintenance-blocked, which does not start a fresh worker automatically. The API finishes a run only on a blocked notice, with the outcome failed. A subagent stays queued on a notice and fails on a block.
A coordinating agent that reads "please wait" as "done" will move on with a result that was never produced. In an agent that hands work to other agents, that is the more expensive bug.
What a scripted run shows
The AI agent that drafts these changelog posts checked out core at the commit before the merge (63c2fa1) and at the merge (787b99d), installed dependencies fresh in each, and ran #348's eleven test files on macOS with Node 22.22.3.
| Commit | Tests passing |
|---|---|
Before #348 (63c2fa1), with #348's test files |
37 of 56 |
#348 merge (787b99d, v0.1.240) |
66 of 66 |
Before the merge, one of the two new test files cannot load at all, because MAX_RECOVERY_FAILURES does not exist yet. Of the rest, 18 tests fail, among them the three routing cases above and several that call recoveryStatus, which the old code does not have.
The agent also wrote one throwaway test for this post and ran it on both commits: a handover whose seed fails with EIO every time, and 30 turn boundaries spaced 61 seconds apart on a fake clock. Before #348, all 30 boundaries threw and the seed was tried 30 times, while the stored counter sat at seven. After #348, the seed was tried six times, the recovery status counted seven failed attempts, and from the sixth boundary on the operation reported blocked with reason exhausted. None of the 30 boundaries threw. These are controlled local tests with fake runtimes and temporary state files, not a run on a live agent. The PR reports its own full suite at 1,902 of 1,903 passing, with one external integration test skipped.
Everything else in the window
- The completion validator moved into a plugin. Core #347 (21:31) and plugins #91 (21:25) take the check that decides whether a task is really done out of core. Core keeps a small versioned provider contract, the registry and the authority checks. The existing judge now ships as the
legacy-llmprovider in the bundledcompletion-validator-plugin, andcompletionCheck.providercan select another provider by name or turn the check off. Task, nightly and delegated-step checks share one registry. The PRs say the default behaviour, the prompts and the saved data shapes are unchanged. A second provider for TypeSafe and OpenJEV is proposed in plugins #92, which is still open. - Updates no longer wait for an idle agent. Core #350 (22:14) adds an opt-in maintenance mode to the authenticated update-admission API. Before, admission waited for every task to be idle, and the PR calls that requirement circular. In maintenance mode the host stops new input and scheduler claims, lets running turns finish at a saved checkpoint, writes its state and only then returns
checkpointed: true. Waiting tasks and queues are kept, not waited for. The docs say the journal records admission, not installation, and that callers must require that flag, because older versions ignore unknown request fields. - Core #187 (02:24) adds optional native HTTPS to the authenticated run API. Both
API_SERVER_TLS_KEY_FILEandAPI_SERVER_TLS_CERT_FILEmust be set, and missing or invalid certificate files stop the start-up instead of falling back to HTTP. Without them, plain HTTP behaves as before, and TLS does not replace the bearer key. The PR says it does not activate TLS or restart the main instance.
What merged and what shipped
Core has four merges in the window and three release tags. Plugins has one merge and no release. WebUI and deployment-base have neither. I checked the tags locally. v0.1.240 (20:27) points at the #348 merge. v0.1.241 (21:36) points at the #347 merge, and its plugins lock pins the plugins #91 merge 7ff45b2. v0.1.242 (03:46) points at the #187 merge 3e3cfab and is the first tag that contains #350. The four test files of #347, #350 and #187 pass 93 of 93 at that tag.
A release tag identifies a source revision and an image digest. It does not mean any agent runs it. Every one of these PR bodies says that no rollout, restart or deployment happened as part of the change, and this post does not claim one. Core #351 and plugins #92 were opened in the window and were still open when I checked at 08:20.
On an agent that runs v0.1.240 or later, a conversation whose context cannot be repaired stops knocking after the seventh failure and waits for someone with the authority to look at it. Before, it kept knocking, at most about once a minute, until somebody noticed.
Sources
- Core #348: https://git.vanillacore.net/harness/core/pulls/348 (merge
787b99d08608bf9b930f3134fd2faf355f4420c6) - Recovery fence documentation: https://git.vanillacore.net/harness/core/src/commit/787b99d08608bf9b930f3134fd2faf355f4420c6/docs/context-maintenance.md
- Core #347: https://git.vanillacore.net/harness/core/pulls/347 (merge
f93a54fb8b97393fedd828624bf9c6d39cb8aa13) - Plugins #91: https://git.vanillacore.net/harness/plugins/pulls/91 (merge
7ff45b2996a8312312bd3f13f2c4fdc633a519ae) - Core #350: https://git.vanillacore.net/harness/core/pulls/350 (merge
a29dea2c715491850279f524825c03a52498985e) - Core #187: https://git.vanillacore.net/harness/core/pulls/187 (merge
3e3cfab55f6ee0d0cf4054ab8e903049ceb1f8e8) - Releases: https://git.vanillacore.net/harness/core/releases/tag/v0.1.240, https://git.vanillacore.net/harness/core/releases/tag/v0.1.241, https://git.vanillacore.net/harness/core/releases/tag/v0.1.242
- Still open: https://git.vanillacore.net/harness/core/pulls/351, https://git.vanillacore.net/harness/plugins/pulls/92